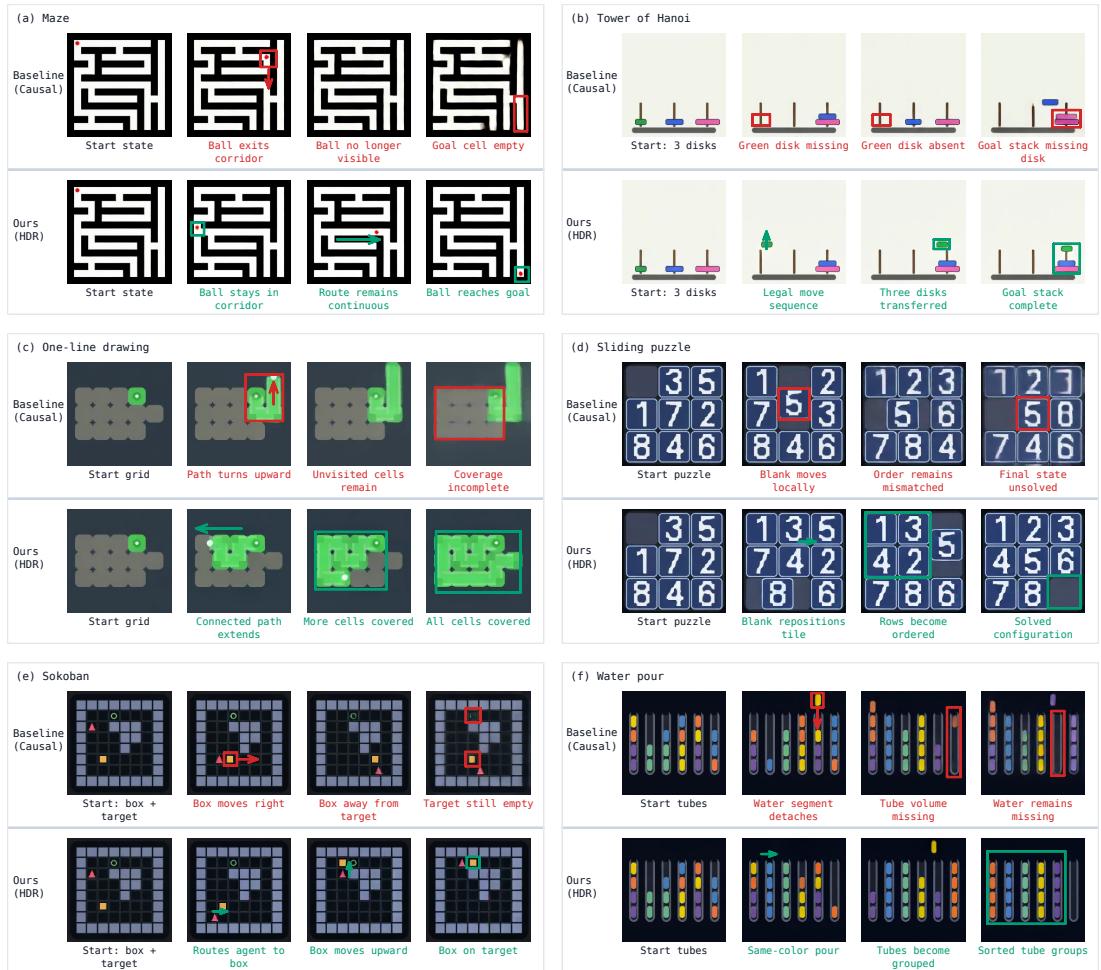
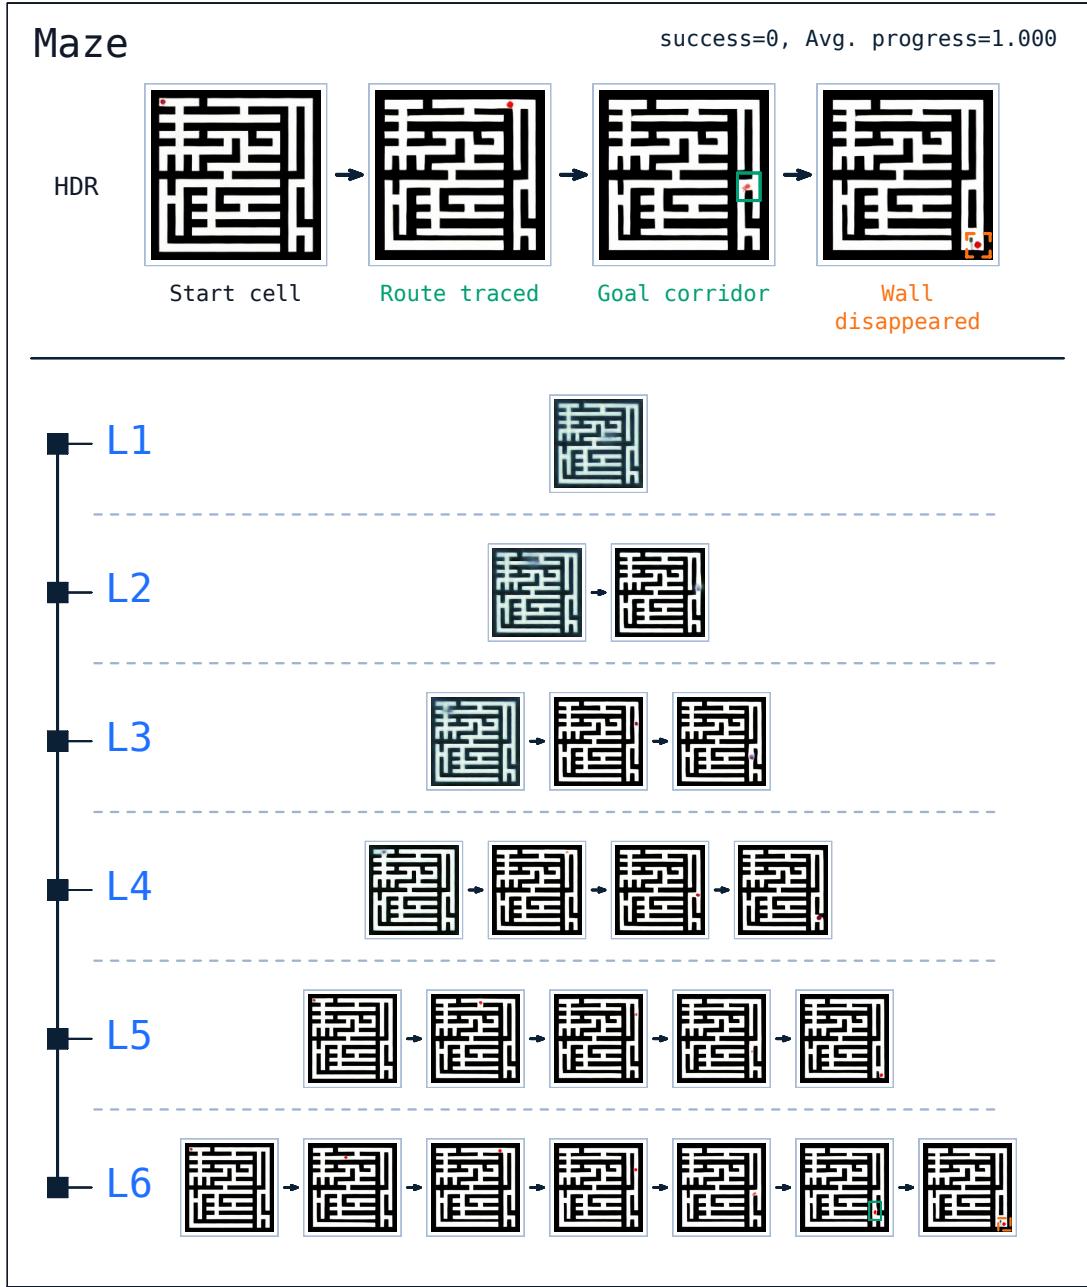
Figureure 11 · : Qualitative comparison across all six reasoning tasks where the streFigure 11: Qualitative comparison across all six reasoning tasks where the streaming autoregressive diffusion baseline fails but HDR succeeds. For each task, the top row shows CausalForcing and the bottom row shows HDR. Red boxes and arrows mark the baseline’s failure points, while green boxes and arrows highlight HDR’s successful coarse-to-fine refinement. Across tasks, the baseline typically commits to an early local mistake, such as leaving the valid maze corridor, missing a required disk transfer, breaking path continuity, misplacing the blank tile, pushing the box away from the goal, or violating water-pouring constraints. In contrast, HDR maintains globally consistent task structure and reaches the correct final state.这张图/表用于判断 Hierarchical Denoising For Multi-Step Visual 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 12 · : Maze failure case of HDRFigure 12: Maze failure case of HDR. The model traces a plausible route and reaches the goal corridor, but a wall disappears near the end of the rollout, producing an invalid maze state despite otherwise correct multi-step planning.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Hierarchical Denoising For Multi-Step Visual 的方法或实验,请结合正文精读段落一起看。