通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-07-21 图像表征 · VFM · JEPA · 视频预训练
arXiv new/cross; audio-visual JEPA SSL · P0 · 2026-07-21

AV-JEPA:它和通用视觉自监督的关系在于:用 early-fusion ViT、modality dropout masking 和 SIGReg,把 JEPA 扩展到音视频 latent 对齐,同时保持无 decoder/无负样本...

高相关;详见方法、贡献和实验边界。

编号2607.15295 优先级P0 类别arXiv new/cross; audio-visual JEPA SSL 会议arXiv new/cross; audio-visual JEPA SSL 方法用 early-fusion ViT、modality dropout masking 和 SIGReg,把 JEPA 扩展到音视频 latent 对齐,同时保持无 decoder/无负样本的简洁自监督结构 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:用 early-fusion ViT、modality dropout masking 和 SIGReg,把 JEPA 扩展到音视频 latent 对齐,同时保持无 decoder/无负样本... 高相关;详见方法、贡献和实验边界。

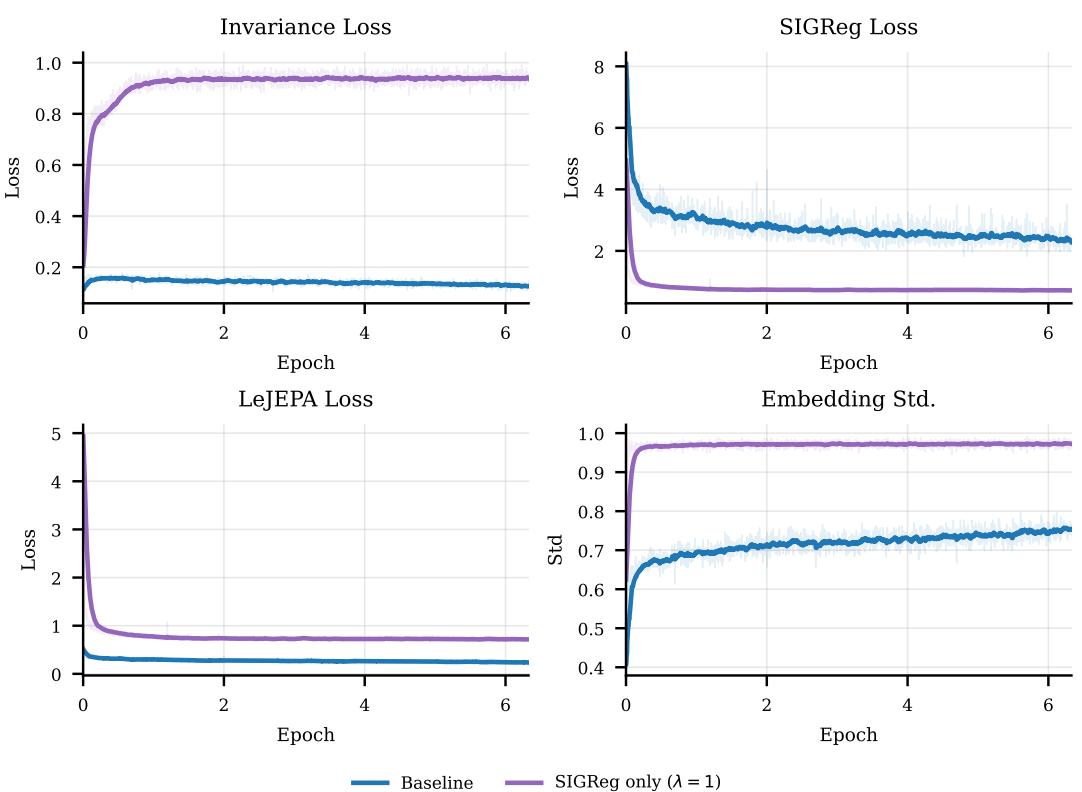
Figureure 17 · Removing the invariance loss ( $\lambda=1$ ) vs
Figureure 17 · Removing the invariance loss ( $\lambda=1$ ) vsFigure 17. Removing the invariance loss ( $\lambda=1$ ) vs. the baseline ( $\lambda=0.05$ ) on VGGSound pretraining. SIGReg alone drives the embedding standard deviation to its target, but the invariance loss never decreases, indicating that the model never learns to align global and local views without the invariance term.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 AV-JEPA 的方法或实验,请结合正文精读段落一起看。
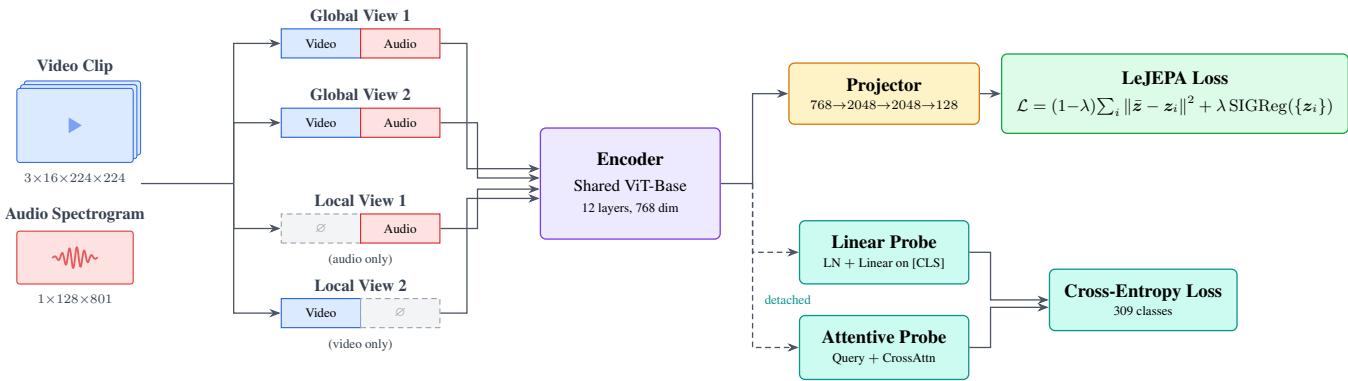
Figureure 1 · AV-JEPA training pipeline
Figureure 1 · AV-JEPA training pipelineFigure 1. AV-JEPA training pipeline. Each clip is split into G=2 global views (both modalities) and K=2 local views (alternating audio-only / video-only, the absent modality zeroed). All views go through a shared ViT-Base early-fusion encoder over video tubelets and audio mel-spectrogram patches. The LeJEPA loss pulls every view embedding toward the joint-modality center $\bar{z}$ while SIGReg enforces an isotropic Gaussian embedding distribution. During VGGSound pretraining we additionally attach detached linear and attentive classification probes.这张图概括 AV-JEPA 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
核心问题

它和通用视觉自监督的关系在于:用 early-fusion ViT、modality dropout masking 和 SIGReg,把 JEPA 扩展到音视频 latent 对齐,同时保持无 decoder/无负样本的简洁自监督结构。

方法拆解

用 early-fusion ViT、modality dropout masking 和 SIGReg,把 JEPA 扩展到音视频 latent 对齐,同时保持无 decoder/无负样本的简洁自监督结构

主要贡献

高相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。