MLLM-DataEngine:它和通用视觉自监督的关系在于:让评测 bad cases 反向驱动增量多模态指令数据生成,是 VLM 训练数据闭环的一种工程模板
中相关;详见方法、贡献和实验边界。
MLLM-DataEngine: Closing the Loop of Multimodal Instruction Tuning Data Generation arXiv new/cross; ICME 2026; MLLM data engine 原文链接
编号2607.15299优先级P3类别arXiv new/cross; ICME 2026; MLLM data engine会议arXiv new/cross; ICME 2026; MLLM data engine方法让评测 bad cases 反向驱动增量多模态指令数据生成,是 VLM 训练数据闭环的一种工程模板来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:让评测 bad cases 反向驱动增量多模态指令数据生成,是 VLM 训练数据闭环的一种工程模板。 中相关;详见方法、贡献和实验边界。
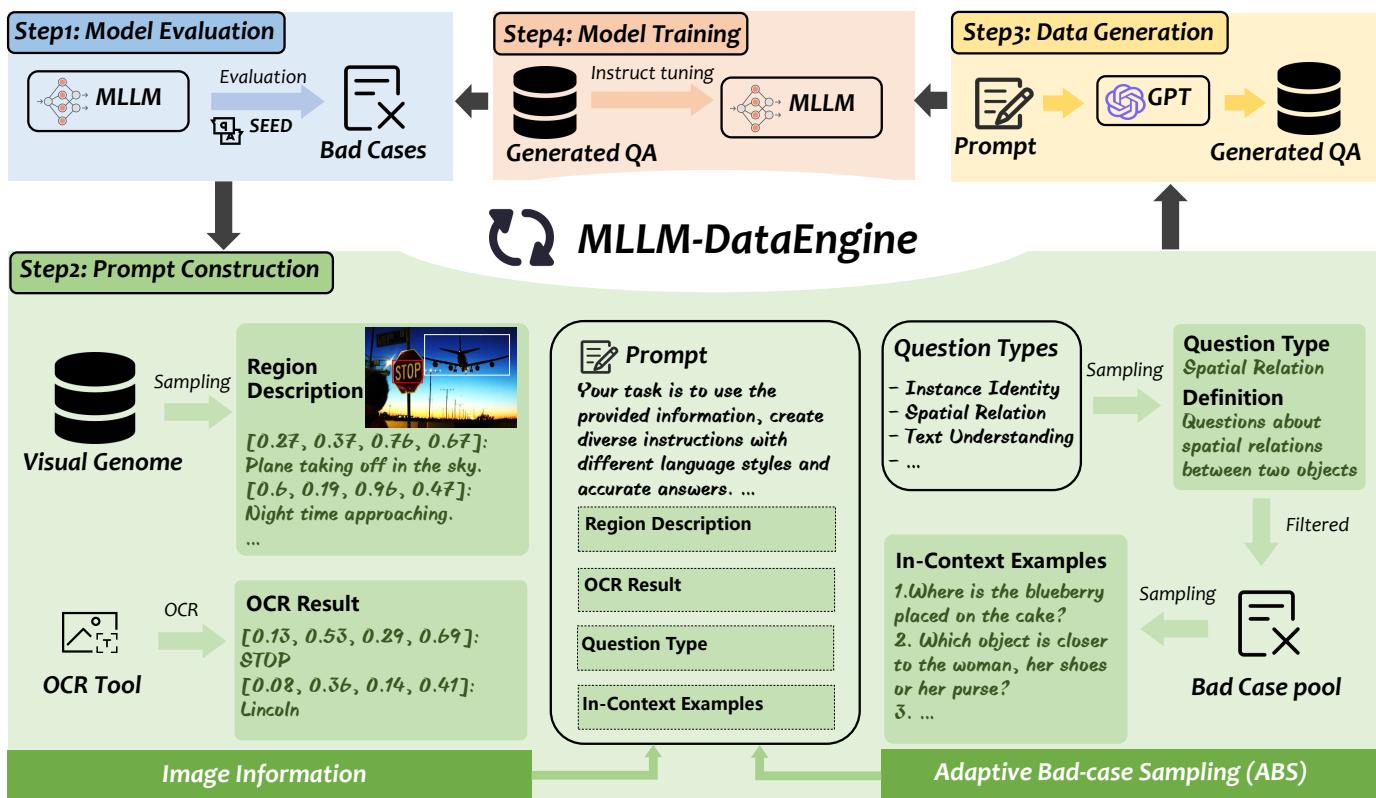
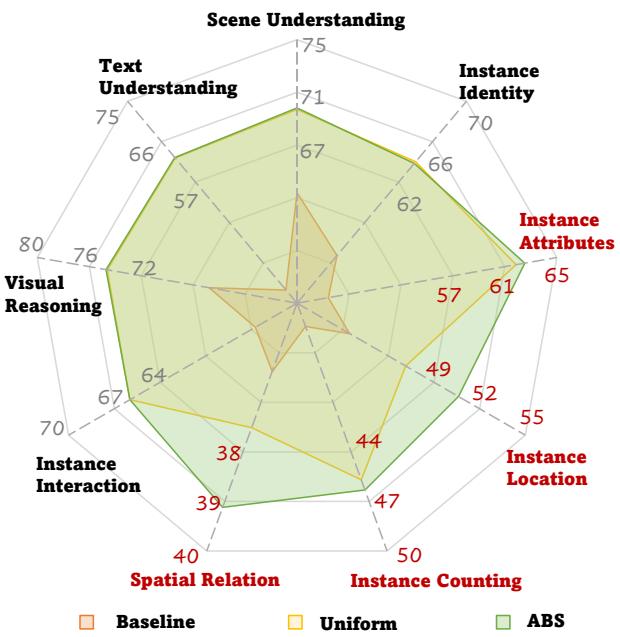
Figureure 2 · : Illustration of proposed MLLM-DataEngineFig. 2: Illustration of proposed MLLM-DataEngine. The whole process is divided into 4 steps. (1) Model Evaluation. We first test the base model on the public benchmark to get the bad cases and build the bad case pool. (2) Prompt Construction. After bad cases are obtained, Adaptive Bad-case Sampling (ABS) is proposed to select the proper question type and the most representative in-context examples. Meanwhile, rich image information is provided. (3) Data Generation. Constructed prompt are fed to GPT-4 to generate data. (4) Model Training. The model is fine-tuned on the latest generated data and loops back to the beginning of the data engine这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 MLLM-DataEngine 的方法或实验,请结合正文精读段落一起看。Figureure 4 · : Comparison between uniform sampling and Adaptive Bad-case Sampling (Fig. 4: Comparison between uniform sampling and Adaptive Bad-case Sampling (ABS). Weak capabilities of the baseline model are highlighted.这张图/表用于判断 MLLM-DataEngine 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:让评测 bad cases 反向驱动增量多模态指令数据生成,是 VLM 训练数据闭环的一种工程模板。