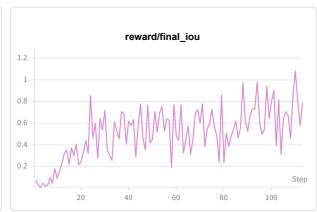
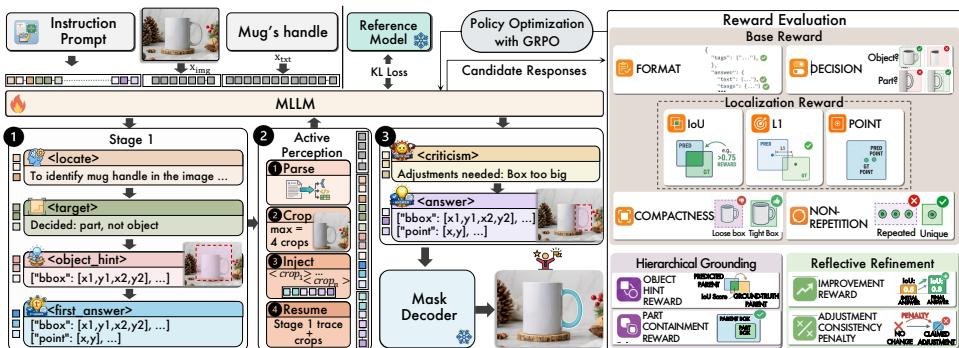
Figureure 6 · : Training curves for the ablated improvement reward variant in which Fig. 6: Training curves for the ablated improvement reward variant in which the external baseline IoU is excluded, reducing the improvement term to $\max(0, R_{\text{IoU}}^{\text{final}} - R_{\text{IoU}}^{\text{initial}})$ . The $x$ -axis shows training steps. Panels show (left) initial-answer IoU (initial\_iou), (center) improvement reward (reward/improvement), and (right) final-answer IoU (reward/final\_iou). After an initial rise, the initial-answer IoU collapses toward 0 as the model learns to produce deliberately poor first predictions in order to inflate the improvement margin - a form of reward exploitation. The full formulation (Section 3.5), which competes against the stronger of the model's own first answer and the scaled external baseline, eliminates this collapse.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Reasoning-Guided Part-Level Visual Grounding via 的方法或实验,请结合正文精读段落一起看。Figureure 2 · : Overview of the action steps and reward evaluation for OP-HRG.Fig. 2: Overview of the action steps and reward evaluation for OP-HRG.这张图概括 Reasoning-Guided Part-Level Visual Grounding via 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。