Are All Tokens Necessary for:它和通用视觉自监督的关系在于:任务是 VPR,但系统评测 token pruning/merging 对 ViT/VFM 检索性能和吞吐的影响,可作视觉 token 效率背景
中相关;详见方法、贡献和实验边界。
Are All Tokens Necessary for Visual Place Recognition? An Empirical Study of Token Reduction for Efficient Inference arXiv new; ViT/foundation-model token reduction 原文链接
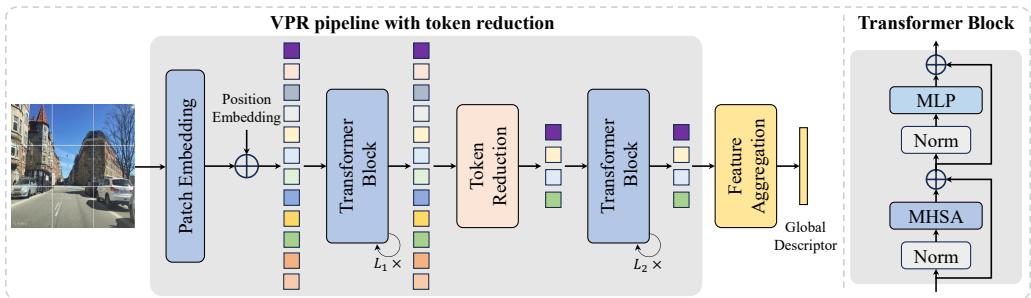
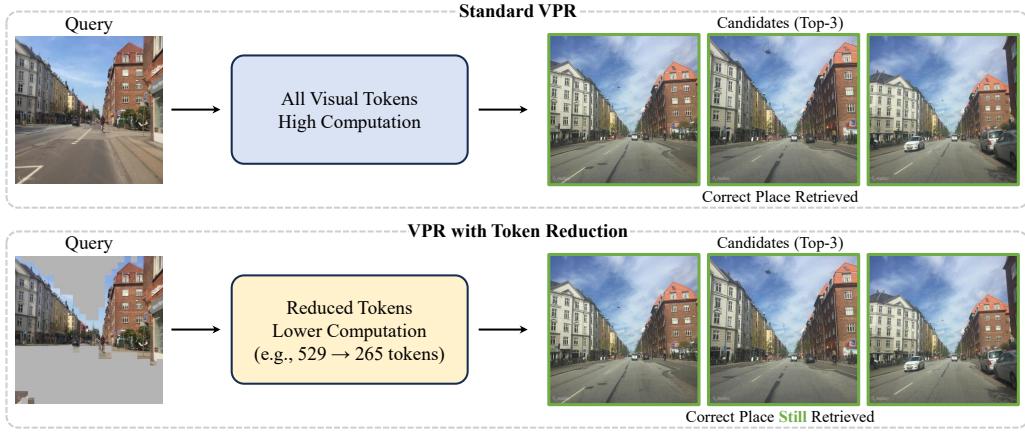
Figureure 2 · Overview of the VPR pipeline with token reductionFig. 2 Overview of the VPR pipeline with token reduction. The input image is divided into patches and encoded as a token sequence. After passing through $L _ { 1 }$ transformer blocks, a token reduction module removes or merges redundant tokens, and the reduced sequence is processed by the remaining $L _ { 2 }$ blocks before being aggregated into a global descriptor for retrieval. The detailed structure of each transformer block is shown on the right.这张图概括 Are All Tokens Necessary for 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · Illustration of token reduction for visual place recognitionFig. 1 Illustration of token reduction for visual place recognition. In standard VPR, the query image is encoded into a sequence of visual tokens, which are then processed and aggregated into a globa descriptor for retrieval. However, in token-reduced VPR, redundant tokens (denoted by gray patches “ ”) corresponding to less informative regions are removed, while landmark-related tokens tend to be preserved. The correct place can still be retrieved despite using fewer tokens.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Are All Tokens Necessary for 的方法或实验,请结合正文精读段落一起看。