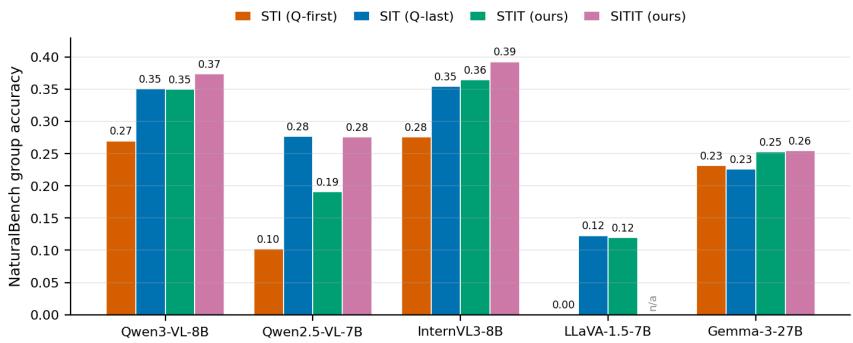
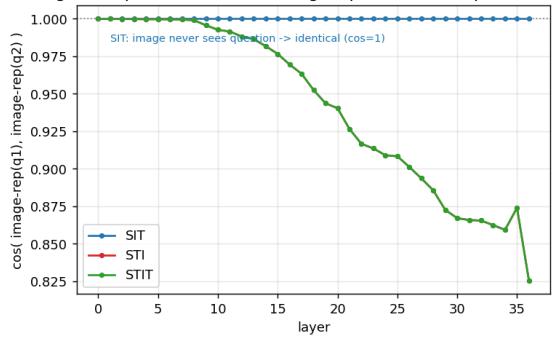
Figureure 6 · : The position ladder, across modelsFig. 6: The position ladder, across models. NaturalBench group accuracy for the five VLMs. On the four models with a paradox, accuracy climbs from question-first (<sup>STI</sup>) to question-last (<sup>SIT</sup>) to echoing (<sup>STIT</sup>) to image re-presentation (<sup>SITIT</sup>); the exceptions are honest and visible (Qwen2.5-VL under-recovers at <sup>STIT</sup>; Gemma-3 has no <sup>STI</sup>-<sup>SIT</sup> gap but still gains from echoing; LLaVA-1.5 is single-image, so <sup>SITIT</sup> is n/a). Exact per-metric numbers for all models are in Tab. 7.这张图/表用于判断 Ask Twice, Look Twice 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 9 · : Same image, two questionsFig. 9: Same image, two questions. Per-layer cos between the image-token representations under $q _ { 1 }$ and $q _ { 2 } .$ . Image-first (blue) stays at 1.000 (the image never sees the question, so its encoding is question-invariant); question-first <sup>STI</sup>/<sup>STIT</sup> (red under green, identical curves) falls to 0.825 (the question rewrites the image). This is a scalar, not a spatial, efect (see Fig. 10).这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Ask Twice, Look Twice 的方法或实验,请结合正文精读段落一起看。